Disaster Recovery and Failover on Confluent Cloud
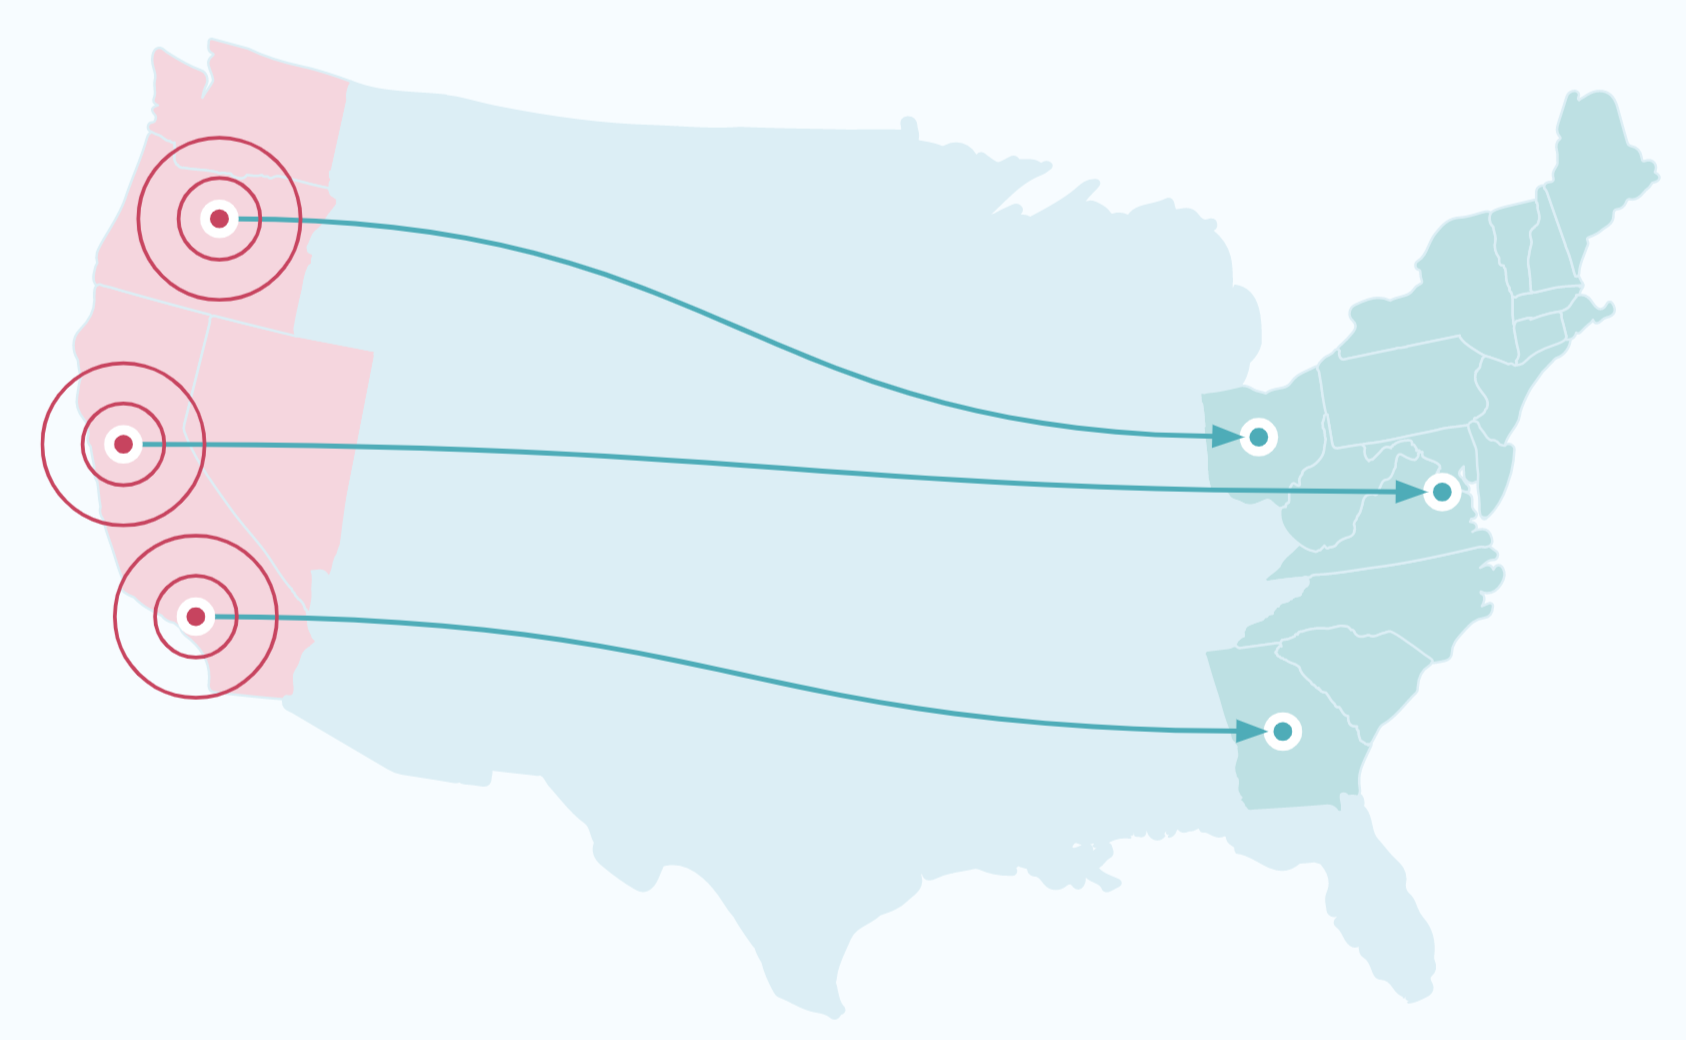
A Disaster Recovery (DR) plan helps your organization quickly recover from regional outages and minimize downtime and data loss. In the public cloud, outages and downtime can cause businesses to lose considerable revenue or halt operations entirely. A solid DR strategy helps ensure business continuity.
If your business depends on Apache Kafka® to run mission-critical workloads or customer-facing applications, then you need a cross-region DR plan for your Kafka deployment. Disaster can take the form of a catastrophic hardware or software failure, power outage, denial-of-service attack, or any other event that causes degradation or failure of an entire cloud region. With a cross-region DR plan, when disaster strikes, your Kafka architecture continues to run in another region until service is restored.
Goal of disaster recovery
The goal of disaster recovery (DR) is to maintain an up-to-date replica of your primary cluster’s data and metadata on a separate DR cluster, so that producers and consumers can switch over with low downtime and minimal data loss when an outage occurs.
Recovery time objectives (RTOs) and recovery point objectives (RPOs)
Recovery Time Objective (RTO) is the maximum acceptable downtime during an outage. Recovery Point Objective (RPO) is the maximum acceptable data loss. Both metrics drive the design of your disaster recovery plan with Cluster Linking.
An RTO shows the difference between when the outage occurs and when your system is back up and running. An RPO measures the difference between the last message produced to the failed cluster and the last message replicated to the DR cluster.
Term |
Description |
|---|---|
Recovery Point Objective (RPO) |
RPO is the point in the data’s history that a failover must resume from. That is, how much data can be lost during a failure. To achieve low RPO, you can use asynchronous replication like Cluster Linking. To achieve zero RPO, you must use synchronous replication, which is not supported by Confluent Cloud. |
Recovery Time Objective (RTO) |
RTO is the amount of time that can elapse while a failover takes place. That is, how long a failover can take. To achieve low RTO, you must have seamless client failover. To achieve zero RTO, you must use an active/active setup. |
Region |
A synonym for a datacenter. |
Disaster Recovery (DR) |
Umbrella term that encompasses architecture, implementation, tooling, policies, and procedures that all allow an application to recover from a disaster or a full region failure. |
Event |
A single message produced to or consumed from Confluent Cloud or Confluent Platform. |
Millisecond (ms) |
1/1,000th of a second. |
Choose your DR deployment strategy
Before implementing Cluster Linking for DR, determine which deployment pattern fits your architecture, and aligns with your recovery point objective (RPO), recovery time objective (RTO), and application requirements.
Feature / Consideration |
Active-Passive (Automatic Failover) (Early Access) |
||
|---|---|---|---|
Primary Use Case |
Single active region; secondary acts as an automated warm standby for DR. |
Single active region; secondary acts as a manually managed warm standby. |
Both regions actively produce and consume traffic simultaneously. |
Failover Mechanism |
Managed Automatic Failover with a single global bootstrap URL. |
Manual failover execution using custom DNS updates, load balancers, or configuration changes. |
Manual failover or application-level client traffic redirection. |
Client Code Changes |
None (Clients use global bootstrap endpoint with auto-DNS resolution). |
Requires client application restarts, configuration updates, or custom discovery logic. |
Requires multi-cluster connection handling or client re-bootstrapping. |
Topic Architecture |
Primary topics mirrored to secondary ( |
Primary topics mirrored to secondary. |
Bidirectional topic replication across both clusters. |
Supported Automatic Failover Features |
Full automated one-click switchover, restore, and pairing orchestration. |
Not supported (uses standard Cluster Linking CLI/API). |
Automatic Failover features (global endpoint, one-click switchover) are not supported. |
Confluent Cloud supports two primary DR implementations:
A one-click solution that automatically switches all clients to the secondary cluster on demand. It enables a deployment to achieve a low RTO. The Automatic Failover Tutorial covers this workflow. Currently available only on active-passive deployments, this option is recommended for active-passive setups.
A manual solution that lets you manage switching your clients to the secondary cluster. The RTO that you can achieve depends on your own tooling and failover procedures. This solution is available on both active-passive and active-active deployments. These workflows are covered in Manual Switchover for Active-Active Deployments and Manual Switchover for Active-Passive Deployments.
With manual switchover, the RTO you can achieve with Cluster Linking depends on your tooling and failover procedures, because failing over your applications is your responsibility. There’s no set minimum or maximum RTO.
The RPO you can achieve with Cluster Linking is determined by the mirroring lag between the DR cluster and the primary cluster. Mirroring lag is exposed through the Metrics API, CLI, REST API, and Confluent Cloud Console.
For the list of clusters that support Cluster Linking, see supported cluster types.
Set up a disaster recovery cluster
For the DR cluster to be ready to use when disaster strikes, it needs to have an up-to-date copy of the primary cluster’s topic data, consumer group offsets, and access control lists (ACLs):
The DR cluster needs up-to-date topic data so that consumers can process messages that they haven’t yet consumed. Consumers that are lagging can continue to process topic data while missing as few messages as possible. Any future consumers you create can process historical data without missing any data that was produced before the disaster. This helps you achieve a low Recovery Point Objective (RPO) when a disaster happens.
The DR cluster needs up-to-date consumer group offsets so that when the consumers switch over to the DR cluster, they can continue processing messages from the point where they left off. This minimizes the number of duplicate messages the consumers read, which helps you minimize application downtime. This helps you achieve a low Recovery Time Objective (RTO).
The DR cluster needs up-to-date ACLs so that the producers and consumers can already be authorized to connect to it when they switch over. Having these ACLs already set and up-to-date also helps you achieve a low RTO.
Note
When using Schema Linking: To use a mirror topic that has a schema with Confluent Cloud ksqlDB, broker-side schema ID validation, or the topic viewer, make sure that Schema Linking puts the schema in the default context of the Confluent Cloud Schema Registry. To learn more, see How Schemas work with Mirror Topics.
Setting up a disaster recovery (DR) architecture depends on which pattern you deploy: an active-passive pattern using managed Automatic Failover, an active-passive pattern using manual switchover, or an active-active pattern using manual switchover.
Considerations for active-passive and active-active implementations
In active-passive deployments, the primary cluster contains data in its topics and metadata used for operations, like consumer offsets and ACLs. The primary cluster handles all write operations while the DR cluster remains in a standby mode, ready to take over in case of an outage. You use Cluster Linking to create a DR cluster in a different region or cloud. When an outage hits the primary cluster, the DR cluster has an up-to-date copy of your data and metadata in the form of mirror topics, allowing producers and consumers to continue running.
In active-active deployments, multiple clusters are active simultaneously, with producers writing data to all active clusters. Each cluster contains its own data and metadata, and Cluster Linking ensures that changes are mirrored across all clusters. This setup provides higher availability but requires careful management of data consistency and conflict resolution.
As a best practice for either active-passive or active-active deployments, create all cluster links for DR in Bidirectional mode. This enables critical metadata features for Cluster Linking.
Resource synchronization in disaster recovery setups
The following resource sync behavior applies to Cluster Linking disaster recovery setups:
ACLs: Synchronized only when the cluster link sets
acl.sync.enable=true(the default isfalse). A link that usescluster.link.prefix(common in active-active deployments) cannot sync ACLs. For the dedicated ACL-sync-link workaround, see Set up security in the Active-Active Deployments section.Consumer group offsets: Synchronized only when the cluster link sets
consumer.offset.sync.enable=true.Topic Configurations: Synchronized from source topics to their mirror topics.
Note
While in a failed-over state, mirror topics are not visible through Automatic Failover interfaces. Configuration changes to mirror topics during an outage must be made directly on the active cluster with the API, CLI, or Cloud Console.
Cluster configurations: Kept aligned automatically only when the clusters are paired with Automatic Failover. For manual switchover setups, provision these on both clusters yourself.
Service accounts and Global API keys: Organization-scoped, so they apply to both clusters without syncing. Cluster-scoped API keys and role-based access control (RBAC) role bindings are not synced. For every deployment pattern, including Automatic Failover, create role bindings on both clusters ahead of time. Cluster-scoped API keys can’t fail over with Automatic Failover, so use Global API keys or OAuth instead.
Schema Validation: Topic schema validation properties (
confluent.key.schema.validationandconfluent.value.schema.validation) are not replicated by Cluster Linking. You must manually apply these settings to the secondary cluster.
Stream processing recovery (ksqlDB and Kafka Streams)
Cluster Linking does not fail over ksqlDB and Kafka Streams applications automatically. Use the following recovery recommendations for these datasets. These recommendations apply to both self-managed Confluent Platform and Confluent Cloud ksqlDB and Kafka Streams.
General recommendations for ksqlDB and Kafka Streams recovery
A best practice is to run a second ksqlDB application in the DR cluster against the mirrored input topic. This enables a much faster failover, and ensures that the ksqlDB application in the DR cluster has the same state as the original cluster.
Replicate only the input topics to the DR cluster. Do not mirror the internal topics created by Kafka Streams for the following reasons:
Changelogs and output topics can be out of sync with each other because they are replicated asynchronously (race conditions). For windowed processing, some temporary inconsistency may be acceptable, but for other use cases it presents a major problem.
Upstream changelogs can lag behind downstream, resulting in an unexpected and altered application state.
For the DR failover scenario, use one of these strategies:
Recommended: Have a second application running in the DR site reading from the mirrored input topic.
Re-run the application against the DR cluster after failover, and reprocess to rebuild state. This typically results in a slower recovery process because rebuilding state can take time.
KTables
Use Tiered Storage to make sure that data is always retained. If you do this, the mirror topic has all history, and the KTable can be built from history. Configure this from the beginning so the input topic retention does not remove needed historical data.
Another option is to configure compaction on the topic in the original cluster from the beginning. You can use the
min.compaction.lag.msandmax.compaction.lag.msconfigurations to preserve the full X-day history and then compact anything older. In other words, the compaction only runs in the part of the data that is older than the configured lag of X days.Existing applications with a KTable built from an input topic that has already purged data due to retention period can either:
Recommended: Rebuild from the mirror topic and lose the history in the KTable.
(Not advised) Mirror the underlying compacted topic (supporting the KTable) to the DR site. If you configure your applications this way, the risk is that the KTable does not accurately represent the current state due to the asynchronous nature of Cluster Linking replication (changelogs and output topics can be temporarily out of sync), and you must reprocess lagged data (either reproduced, or processed when the original cluster has returned to service). This strategy is not advised but can be tested if absolutely necessary. Confluent Cloud cannot guarantee accurate data representation in the DR cluster with this method.
Recovery after a disaster
If your original cluster experienced a temporary failure, like a cloud provider regional outage, then it may come back.
Note
The steps in this section apply to manual switchover deployments. If you use Automatic Failover, recover any unreplicated data from the original primary cluster before you run the restore step, because restore truncates that data. Then fail back as described in the Automatic Failover tutorial.
Recover lagged data
Because Cluster Linking is asynchronous, you may have had data on the original cluster that did not make it over to the DR cluster at the time of failure.
If the outage was temporary and your original Confluent Cloud cluster comes back online, there may be some data on it that was never replicated to the DR cluster. You can recover this data if you wish.
Find the offsets at which the mirror topics were failed over.
These offsets are persisted on your DR cluster, as long as your cluster link object exists.
Note
If you delete your cluster link on your DR cluster, you lose these offsets.
For any topic that you called failover or promote on, you can get the offsets at which the failover occurred with either of the following methods:
Use this CLI command, and view the
Last Source Fetch Offsetcolumn in the command output.confluent kafka mirror describe <topic-name> --link <link-name>
Use the Confluent Cloud REST API calls to describe mirror topics with either
/links/[link-name]/mirrorsor/links/[link-name]/mirrors/<topic-name>, and look at themirror_lagsarray and the values underlast_source_fetch_offset.
With those offsets in hand, point consumers at your original cluster, and reset their offsets to the offsets you found. Your consumers can then recover the data and act on it as appropriate for their application.
Tip
You can also append these messages to the end of the topics on your DR cluster by using Confluent Replicator.
Move operations back to the original cluster
After failing over your cluster, Kafka clients, and applications to a DR region, the most common strategy is to fail forward (also known as fail and stay). That is, you keep operations running on the DR region indefinitely, converting it to be your new “primary” region, and build up a new DR region. This is because cloud regions are usually interchangeable for businesses running in the cloud that do not have a physical datacenter tying them to a specific geography.
If you have failed over all applications from the original region, you have little to gain by failing back to that region, which would take effort and introduce risk.
On the other hand, some scenarios may require that you move operations back to your original region, perhaps to minimize latency and cost when interacting with datacenters and nodes in that region. If you want to move operations back to your original cluster, here is the sequence of steps to do so.
Recover lagged data.
Recover data that was never replicated.
Pause the cluster link that was going to the DR cluster.
Identify the topics that you wish to move from the DR cluster to the original cluster. If any of these topics still exist on the original cluster, you need to delete them.
Migrate from the DR cluster to your original cluster. Follow the instructions for data migration.
After you have moved all of your topics, consumers, and producers, restore the DR relationship. To do so, delete the topics on the DR cluster, unpause your cluster link, and recreate the appropriate mirror topics (or let the cluster link auto-create them).
Next steps and setup tutorials
After selecting your deployment pattern, proceed to the detailed prerequisites, setup steps, and failover runbook for your chosen strategy: