

Capture and Maintain Your Business with a Streamhouse on Confluent Cloud
The first domain of a Streamhouse is the data and trust layer: you build and protect one current, trusted picture of your business. Each section on this page covers one solution in this domain, who it’s for, and how you build it on Confluent Cloud.
Synchronize a change everywhere it is used
Synchronizing a change everywhere means capturing each change in your business state once and delivering the same update to every system and person that depends on it. No team acts on a stale or conflicting copy, and no integration is built twice.
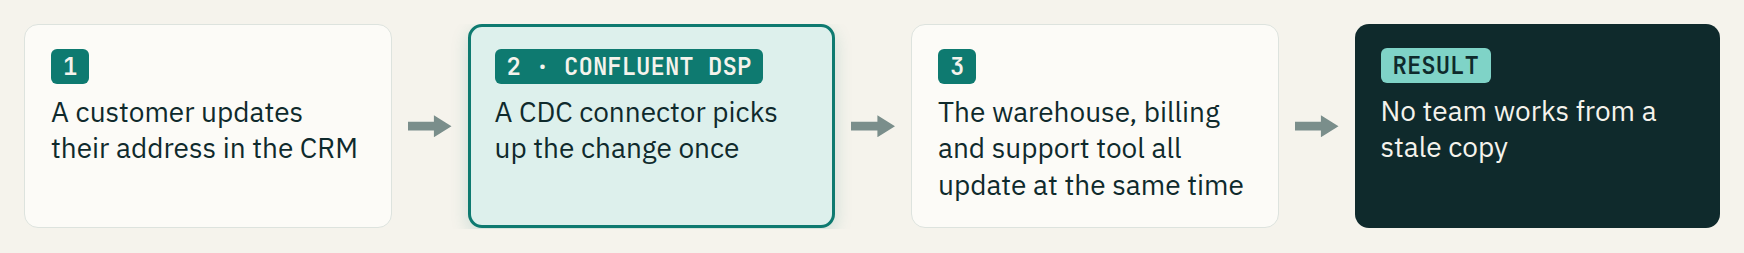
A CDC connector captures an address change once and delivers it to every system that keeps a copy.
To see this pattern end to end, see Start here: the always-current table.
Who needs to synchronize changes
Data engineers, integration developers, and streaming architects who move change out of source systems, such as databases, mainframes, and SaaS applications, into every downstream consumer without rebuilding the integration for each one.
How a Streamhouse synchronizes a change everywhere
Capture change at the source with fully managed connectors and change data capture (CDC). For more information, see Connect to External Services in Confluent Cloud.
Shape and join the change in Confluent Cloud for Apache Flink®, then materialize the result as an always-current table. For more information, see Stream Processing with Confluent Cloud for Apache Flink and Materialized Tables in Confluent Cloud for Apache Flink.
Serve the same state where each consumer needs it: to applications as always-current reads from Lightning Tables, and to analytics as Iceberg or Delta Lake tables with Tableflow. For more information, see Lightning Tables in Confluent Cloud and Tableflow in Confluent Cloud.
Maintain one consistent state across participants
A consistent state is one current value for every key, such as the stock of one SKU or the state of one profile. Every reader sees the same value, and it stays correct through processing changes and maintenance. Transactional systems read this live state without running a separate database.
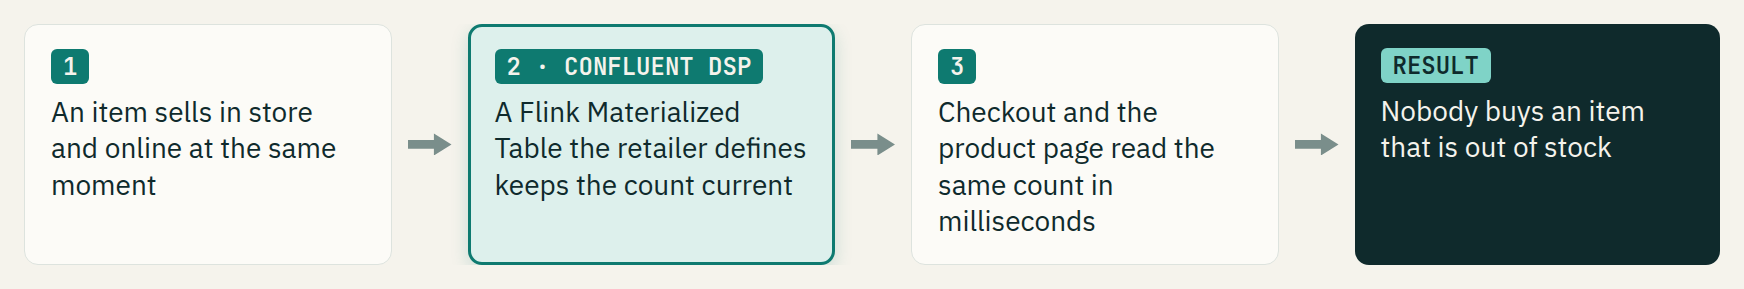
A Flink materialized table keeps one current stock count that checkout and the product page both read.
To see this pattern end to end, see Start here: the always-current table and Quick Start: Build a Streamhouse on Confluent Cloud.
Who needs one consistent state
Backend engineers and platform architects in retail, ecommerce, and logistics who own inventory and product availability
The teams building checkout, product pages, back-in-stock notifications, and replenishment on live state
How a Streamhouse maintains one consistent state
Order every change to a resource on a shared log, keyed so that all participants read changes to the same key in the same sequence. Records with the same key go to the same partition, which is an ordered log, as long as the topic’s partition count is stable and every producer uses the same partitioner. By default, clients in different languages don’t use the same partitioner, so set a common partitioner when producers span languages. Adding partitions also moves keys, which can create duplicate rows in a Tableflow upsert table. For more information, see Manage Topics in Confluent Cloud and Write Modes with Tableflow in Confluent Cloud.
Maintain one current value per key in Confluent Cloud for Apache Flink. A materialized table with a primary key writes in upsert mode and folds each key’s stream of changes into its latest value continuously, so every reader resolves the same current state. For more information, see Stream Processing with Confluent Cloud for Apache Flink and Materialized Tables in Confluent Cloud for Apache Flink.
Serve the latest keyed state for low-latency reads from a Lightning Table, to AI agents, and to applications through Early Access direct API access. For more information, see Lightning Tables in Confluent Cloud.
Isolate service evolution and failure recovery
Isolated evolution and recovery lets one team introduce a new capability or recover from a localized data failure on its own. The team deploys its change or replays only the affected data, without destabilizing other teams or forcing a system-wide rebuild.
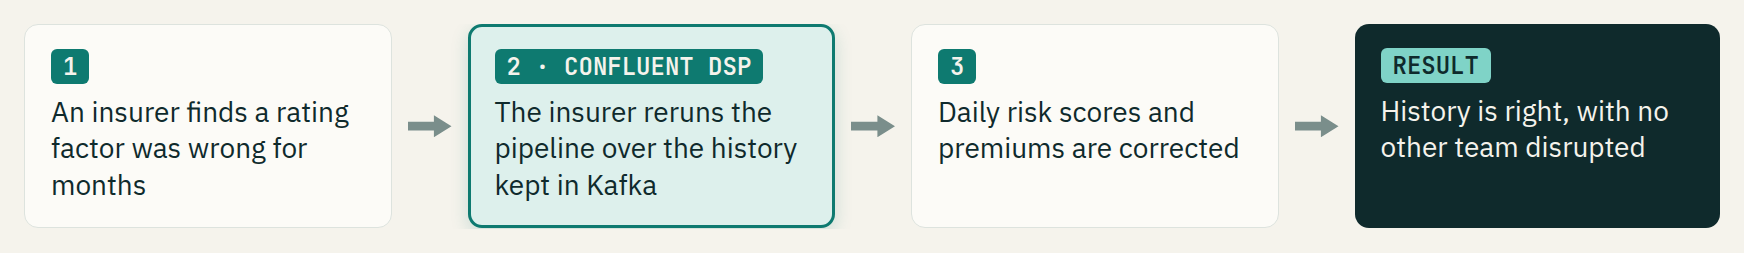
Rerunning the pipeline over the history kept in Apache Kafka® corrects past risk scores without disrupting other teams.
Who needs isolated evolution and recovery
Platform engineers and site reliability engineers (SREs)
Software architects
Data engineers modernizing a legacy estate or running event-driven microservices that communicate only through topics
How a Streamhouse isolates evolution and recovery
Retain and replay change from topics so recovery reprocesses a targeted window of data, not the whole pipeline. For more information, see Manage Topics in Confluent Cloud and retention.ms.
Change logic and correct history by reprocessing in Confluent Cloud for Apache Flink. Change a materialized table’s query and reprocess the source data to apply the new logic to past results. Reprocessing rebuilds the table’s state from the source, so a change to a stateful query costs about as much as building the table again. For more information, see Stream Processing with Confluent Cloud for Apache Flink and Materialized Tables in Confluent Cloud for Apache Flink.
Rebuild a query’s state from history with streaming bootstrap, an Open Preview feature. A new or changed continuous query catches up on historical data in batch mode, which is faster than replaying it through a streaming job, and then switches to processing live data. For more information, see Streaming bootstrap.
Hold the contract between teams in Schema Registry, so a producer evolves its schema within a compatibility mode, and Schema Registry rejects a change that the mode doesn’t allow. A compatible change can still break a query that depends on a specific field, such as renaming an optional field that a join reads, so review schema changes against the queries that read the topic. For more information, see Change subject level (per topic) compatibility mode of a schema.
Replicate topics to another cluster with Cluster Linking, for migration and workload isolation. For more information, see Geo-replication with Cluster Linking on Confluent Cloud.
This solution covers isolated change and targeted replay. For multi-zone high availability, see Resilience in Confluent Cloud. For cross-region disaster recovery and failover, see Disaster Recovery and Failover on Confluent Cloud.
Demonstrate data control without a parallel system
Demonstrating data control means producing evidence of access, lineage, and encryption from the same system that already runs the business. You meet a regulatory or audit requirement without maintaining a separate, slower compliance environment.
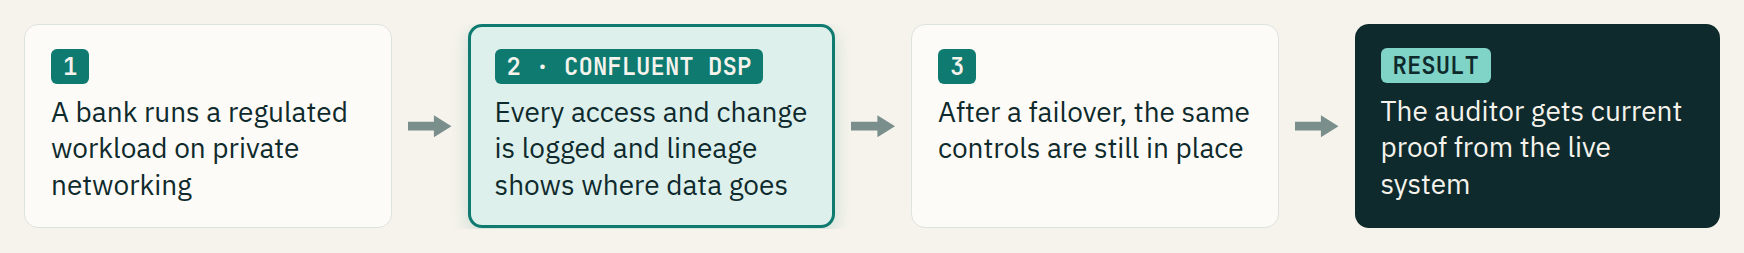
Audit logs and lineage give an auditor current proof of control from the live system.
Who needs to demonstrate data control
Governance, risk, and compliance (GRC) teams
Security operations
Governance engineers in regulated industries and the public sector
How a Streamhouse demonstrates data control
Govern schemas, lineage, and data classification with Stream Governance. For more information, see Stream Governance on Confluent Cloud and Govern Data Streams in Confluent Cloud.
Control and prove who can access what with role-based access control (RBAC) and audit logs. For more information, see Role-based Access Control (RBAC) on Confluent Cloud and Audit Log Concepts on Confluent Cloud.
Encrypt sensitive fields in the stream with client-side field level encryption (CSFLE). For more information, see Protect Sensitive Data Using Client-Side Field Level Encryption on Confluent Cloud.
Use self-managed encryption keys (also known as bring your own key, or BYOK) to protect data at rest on supported cluster types. For more information, see Protect Data at Rest Using Self-Managed Encryption Keys on Confluent Cloud.
For an overview of security on Confluent Cloud, see Manage Security on Confluent Cloud.
Note
This website includes content developed at the Apache Software Foundation under the terms of the Apache License v2.