

Run Your Business with a Streamhouse on Confluent Cloud
The second domain of a Streamhouse is the consumption layer: you turn the current, trusted picture of your business into outcomes. Each section on this page covers one solution in this domain, who it’s for, and how you build it on Confluent Cloud.
Monitor the business to prevent negative impact
Monitoring the business means recognizing a developing failure in a stream of events and intervening while the response is still cheap. The failure might be equipment degradation, a supply-chain bottleneck, or a malicious act such as fraud, intrusion, or abuse. Acting early stops the outage, loss, or breach before it escalates.
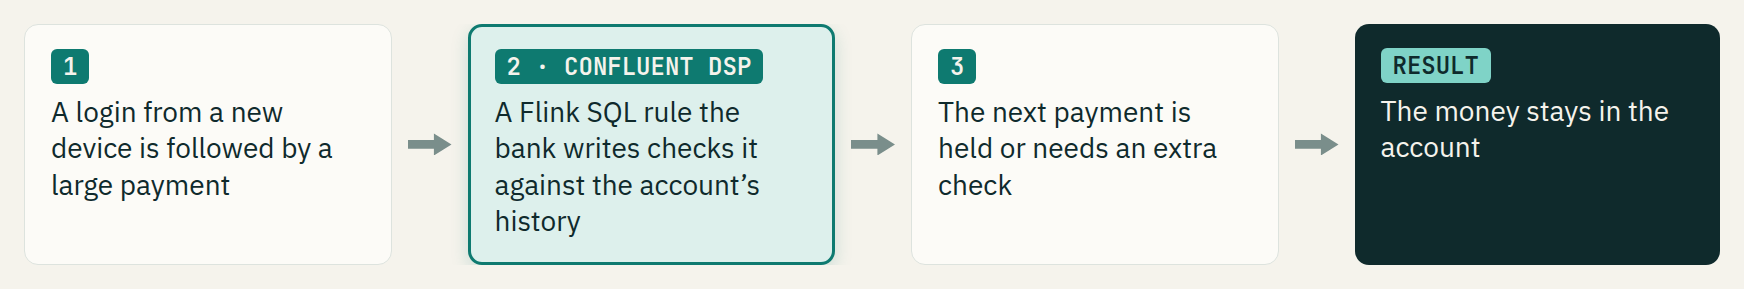
A SQL rule checks each payment against the account’s history and holds a suspicious one.
Who needs to monitor the business
Fraud, risk, and security teams
Plant and network operations
Supply-chain leads
In Confluent Cloud, data engineers build the ingestion. Security and fraud engineers write the detection logic in Flink SQL on Confluent Cloud for Apache Flink®, and IoT engineers bring physical telemetry into the stream.
How a Streamhouse monitors the business
Ingest the signal from transaction databases, network logs, and edge devices with fully managed connectors and change data capture (CDC). For more information, see Connect to External Services in Confluent Cloud.
Enrich each event with current state and detect the pattern in real time with Flink SQL: enrich with temporal and lookup joins, detect anomalies with
ML_DETECT_ANOMALIES, and match multi-event sequences withMATCH_RECOGNIZE. For more information, see Stream Processing with Confluent Cloud for Apache Flink, Join Queries in Confluent Cloud for Apache Flink, ML_DETECT_ANOMALIES, and Pattern Recognition Queries in Confluent Cloud for Apache Flink.Keep the data trustworthy with Schema Registry and role-based access control (RBAC). For more information, see Govern Data Streams in Confluent Cloud and Role-based Access Control (RBAC) on Confluent Cloud.
Retain the decisions and their inputs for audit and later investigation by materializing them to Iceberg or Delta Lake with Tableflow. For more information, see Tableflow in Confluent Cloud.
The detector produces a decision, such as block, step up, or alert, that’s then delivered to the system or person that acts on it. For that hand-off, see Route a computed outcome to its point of action.
Decide across the last five seconds and the last five years
Deciding across live and historical data means computing a decision or an investigative answer from recent activity and the deep historical archive together, in one place. The outcome reflects current reality, not an approximation from last night’s snapshot, without switching between separate tools or waiting on a batch refresh.
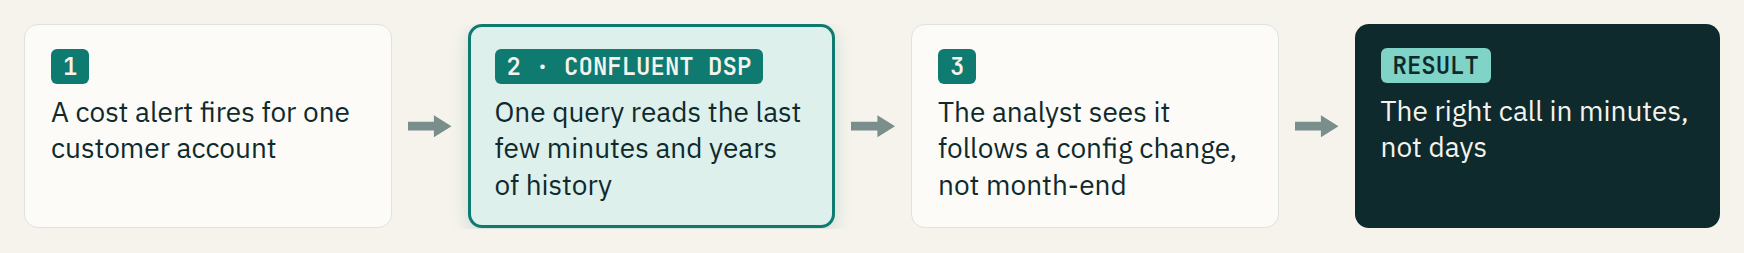
One query reads recent activity and years of history, so the analyst finds the cause in minutes.
To see this pattern end to end, see Quick Start: Build a Streamhouse on Confluent Cloud. For a three-part tutorial that lands trades in Iceberg with Tableflow, queries the history with Spark, and serves live statistics to a dashboard, see Streamhouse for Analytics on Confluent Developer.
Who needs to decide across live and historical data
Underwriters, pricing and marketing teams, analysts and business intelligence (BI) teams
Operational investigations, data engineers, site reliability engineers (SREs), and financial operations (FinOps) leaders
The pattern spans the boundary between live and historical data: the latest minutes exist only in Apache Kafka®, the cause and the multi-year baseline sit in the lakehouse, and one query reads across both.
How a Streamhouse decides across live and historical data
Union live and historical data in one bounded query with Snapshot Queries, which read the latest records from Kafka topics together with historical data in Iceberg tables to return a point-in-time result. For more information, see Snapshot Queries in Confluent Cloud for Apache Flink. To run one, see Run a Snapshot Query with Confluent Cloud for Apache Flink.
Serve the historical side as Iceberg tables with Tableflow. For more information, see Tableflow in Confluent Cloud.
Query from the surface that fits the moment. For more information, see Choose a query surface.
These queries target decisions in seconds to minutes, not sub-second serving. When the finding needs to reach the team or system that acts on it, see Route a computed outcome to its point of action.
Ground and continuously adapt an AI agent
Grounding an AI agent means basing its decisions on the current state of your business and keeping its logic current as real-world conditions change. Its output then reflects what’s true now rather than a stale snapshot.
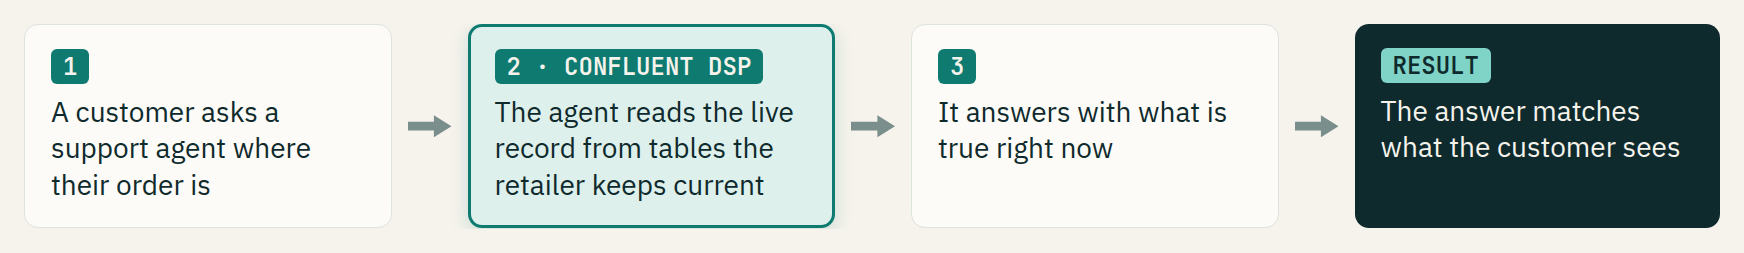
The agent reads the live order record before it answers, so its answer matches what the customer sees.
To see this pattern end to end, see Quick Start: Build a Streamhouse on Confluent Cloud. For a three-part tutorial that builds a Streaming Agent, calls a tool over MCP, and grounds the agent with the Real-Time Context Engine, see Streamhouse for AI Agents on Confluent Developer.
Who needs to ground AI agents
AI and machine learning engineers
Data engineers
Machine learning operations (MLOps) teams shipping agents and copilots that act in place of a person
How a Streamhouse grounds an AI agent
Serve live business context to agents over the Model Context Protocol (MCP) with the Real-Time Context Engine. For more information, see Real-Time Context Engine in Confluent Cloud.
Run models and inference in your streams with Flink SQL. For more information, see Run External Model Inference with Confluent Cloud for Apache Flink.
Build agents that run continuously with Streaming Agents. For more information, see Streaming Agents with Confluent Intelligence in Confluent Cloud.
For an overview of AI capabilities on Confluent Cloud, see Build AI with Confluent Intelligence in Confluent Cloud.
Route a computed outcome to its point of action
Routing an outcome means delivering a decision or insight straight to the system or person responsible for acting on it, without a manual handoff. The action never waits for someone to notice the outcome and forward it.
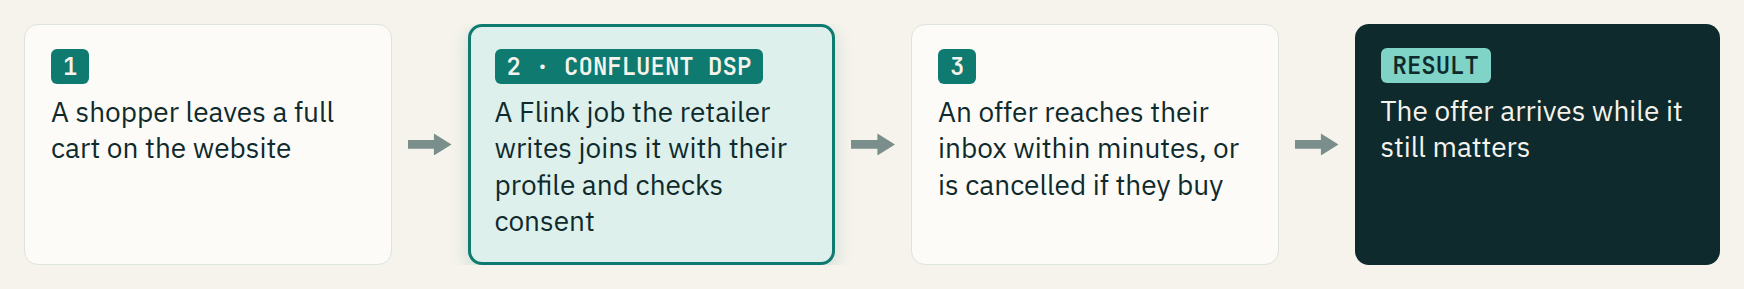
A Flink job turns an abandoned cart into an offer that reaches the shopper within minutes.
Who needs to route outcomes to action
Data engineers
Backend engineers
Integration developers who wire computed decisions into operational systems and workflows
How a Streamhouse routes an outcome to its point of action
Produce the decision in Confluent Cloud for Apache Flink. For more information, see Stream Processing with Confluent Cloud for Apache Flink.
Act on it continuously with Streaming Agents. For more information, see Streaming Agents with Confluent Intelligence in Confluent Cloud.
Push the outcome to operational systems, such as customer relationship management (CRM) systems, ticketing, and webhooks, with fully managed sink connectors. For more information, see Connect to External Services in Confluent Cloud.
Note
This website includes content developed at the Apache Software Foundation under the terms of the Apache License v2.